Where PDF to Word Conversion Breaks, and Why
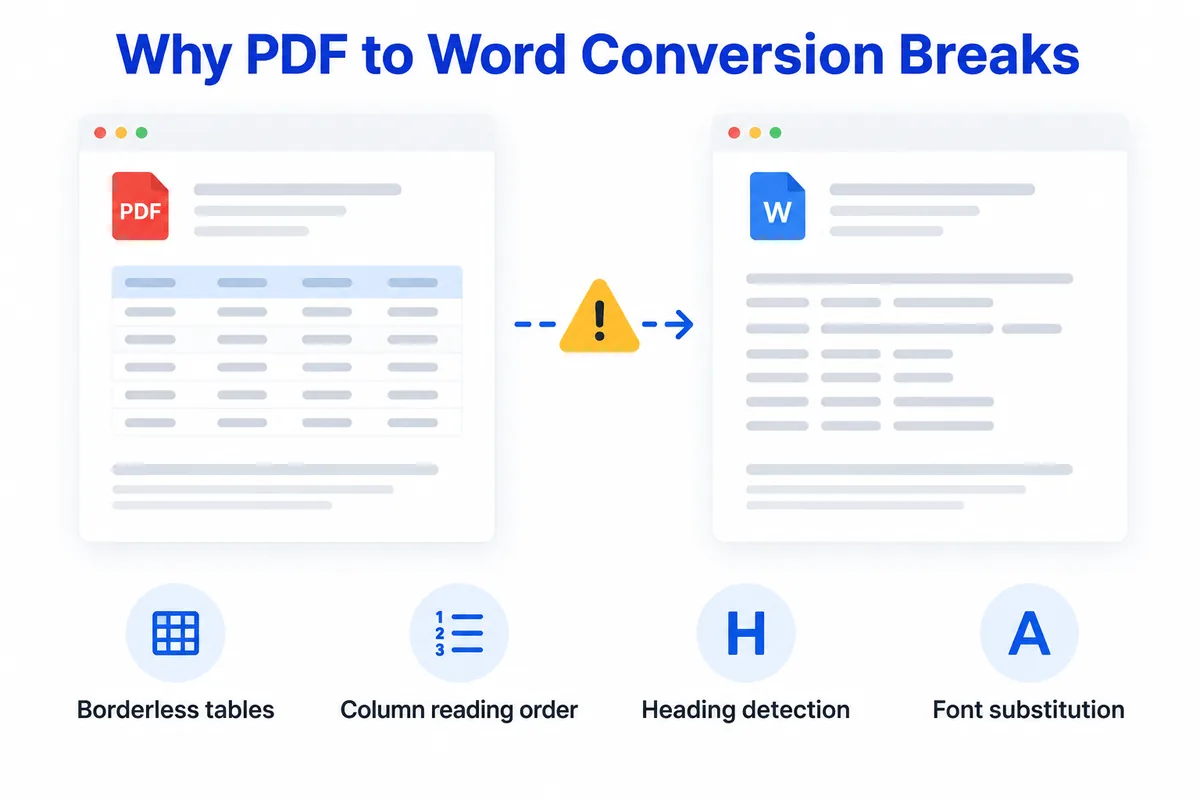
The conversion finishes and the first page looks fine. Then a table has drifted into loose paragraphs and a heading has become body text. Nothing failed outright — and the reason is what a PDF stores in the first place.
Do it now: Convert PDF to Word — the steps in each app.
A PDF describes appearance, not structure
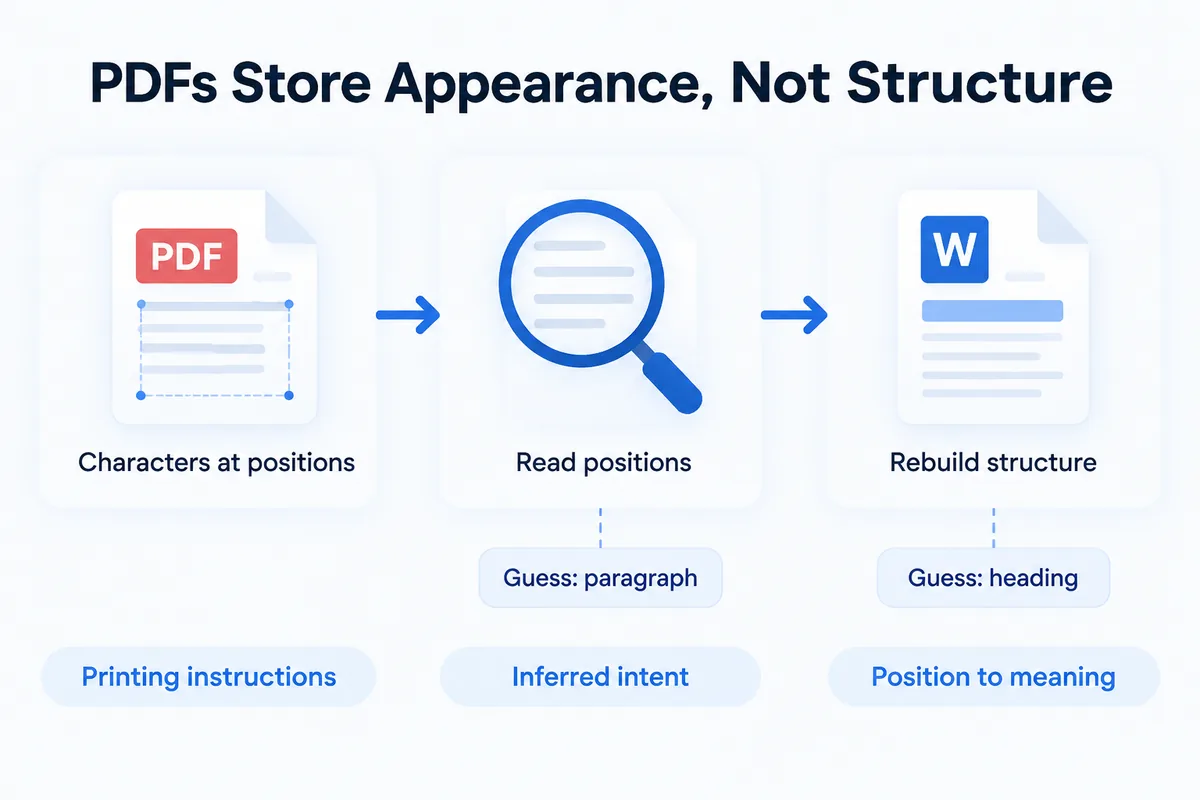
A word processor file records meaning: this is a heading, this is a four-column table. A PDF records printing instructions: put these characters here, in this font, at this size.
So conversion works backwards. It reads positions and infers intent — characters on a baseline are a line, similar spacing means a paragraph, a bigger bolder line is probably a heading. Good inferences, but still inferences. Every place conversion "breaks" is a place the guess had too little to go on.
The places it goes wrong
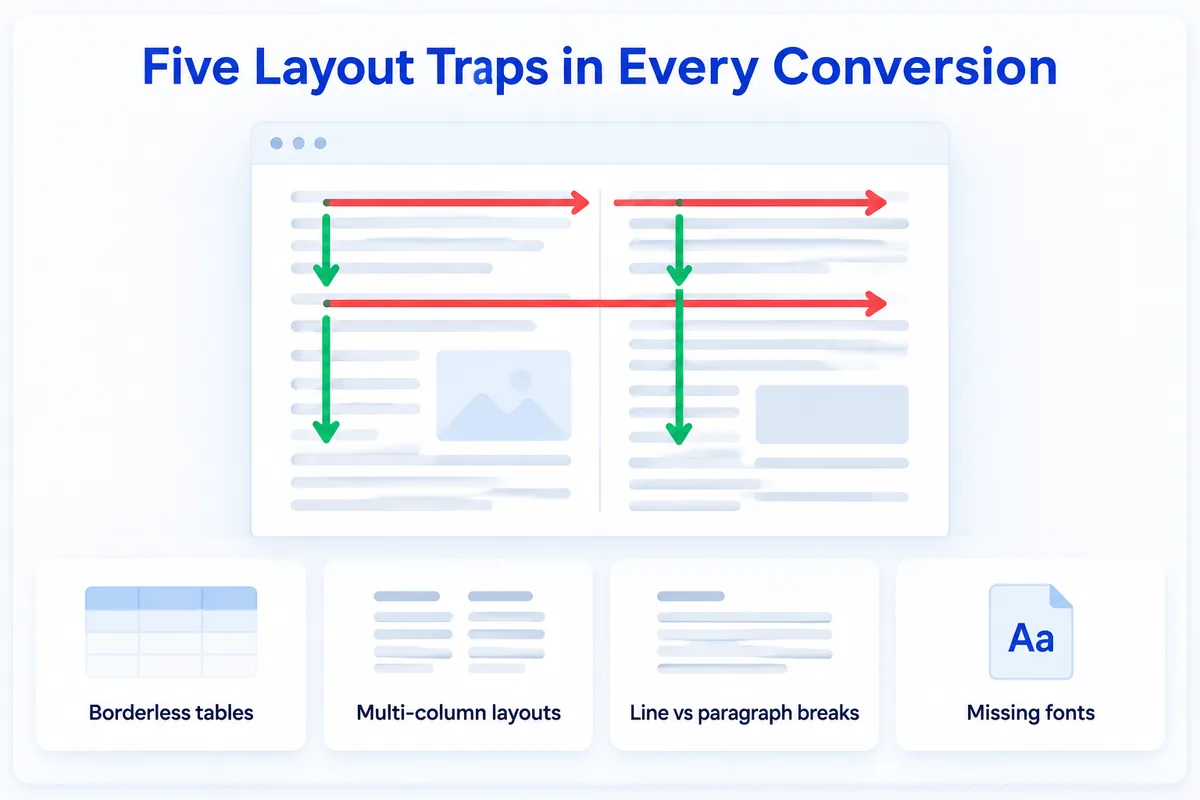
Borderless tables. Drawn lines are the evidence that columns exist. Without them, a table looks exactly like text that happens to line up. The most common complaint by far.
Multi-column layouts. Read across instead of down and sentences from both columns interleave.
Headings that were never headings. Often just a larger, bolder line. Conversion cannot know whether it was a chapter title or an emphasised sentence.
Line breaks becoming paragraph breaks. A PDF stores each visual line separately; deciding which endings are real is a judgement call.
Fonts you do not have. Word substitutes, widths change, and line and page breaks move even when every character is correct.
Footnotes, headers, forms. Separate structures in a word processor, ordinary positioned text in a PDF.
What actually helps
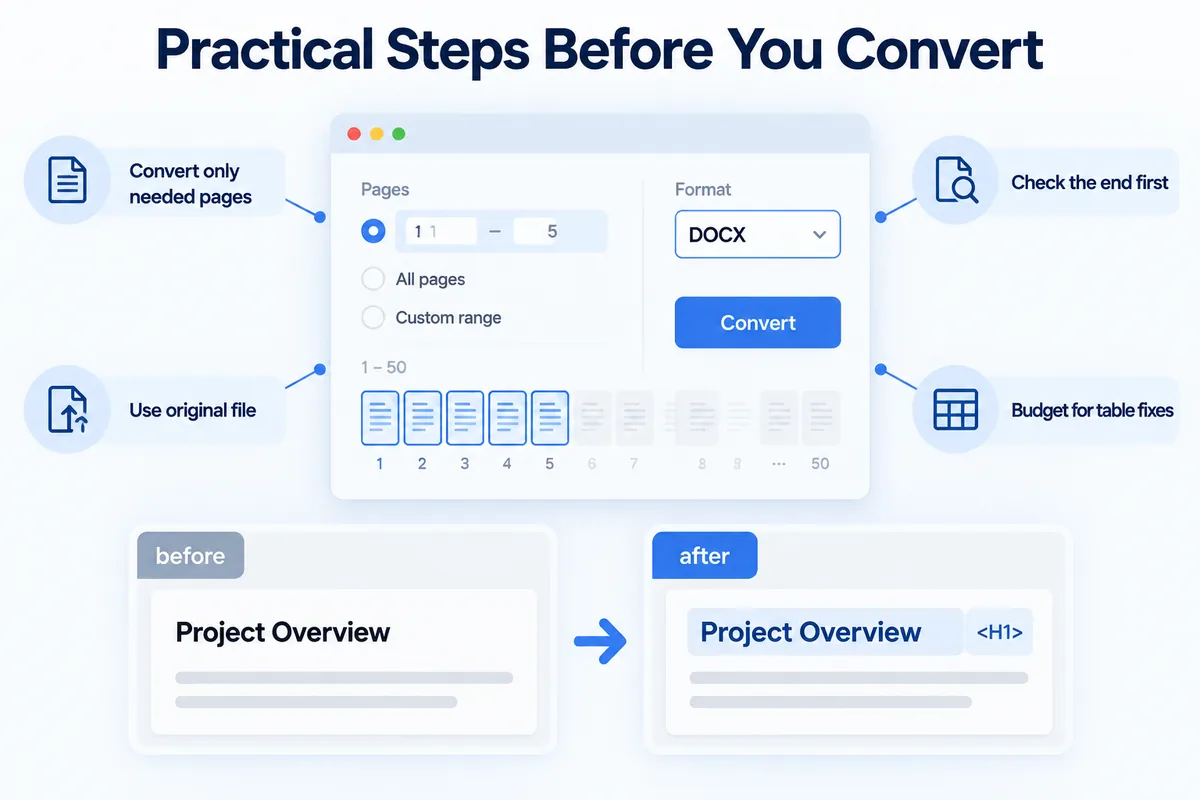
- Use the original file if it still exists. No conversion beats the document the PDF was made from.
- Decide what you need. Want the words? Convert and expect layout work. Want the layout? Editing the PDF directly is often less work. Many "convert this to Word" jobs are really "change three sentences".
- Convert only the pages you need. Five pages convert cleanly and you only check five.
- Budget for tables and headings. Reapplying heading styles takes minutes and fixes the navigation pane and table of contents at once.
- Check the end, not the beginning. Problems accumulate; page sixty is where columns drift.
Common questions
Why did my table become paragraphs? It had no drawn borders.
Text right, layout wrong? Separate steps. Reading characters is the easy half.
Would another format work better? Plain text discards layout deliberately and never surprises you. Spreadsheets convert well when the source table has ruling lines.
Can I convert a protected PDF? Not if the restriction is not yours to lift. Ask the sender for an editable copy.
Why do two tools differ? Where the file records structure, tools agree. Where they must infer it, they diverge.
In short
Conversion is a reconstruction, not a translation. It breaks exactly where the original page carried its meaning visually rather than structurally — borderless tables, columns, headings that were only big text.
That turns the question from "why did this break?" into "what did this page never record?" HanFlow PDF covers conversion, direct PDF editing and text recognition on the desktop, so you can take whichever route is less work.