Why You Cannot Select Text in a Scanned PDF (and How to Fix It)
You try to copy a paragraph and the cursor refuses to land between the letters. Search finds nothing either. Nothing is broken — the file simply does not contain any text.
Do it now: Convert PDF to Word — the steps in each app.
A scanned PDF holds a picture, not letters
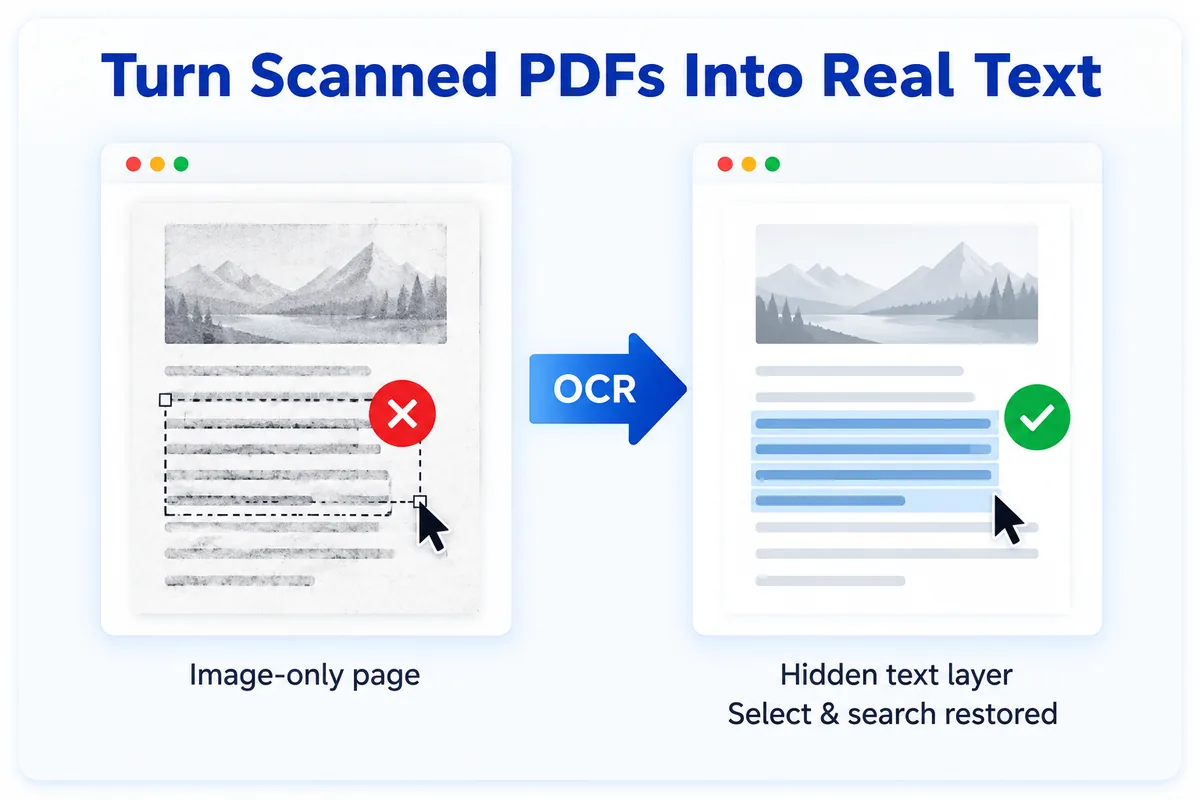
A scanner records brightness values, not characters. What you read as letters is an arrangement of pixels, and a PDF is happy to carry a picture as its only content.
So three things vanish at once: there is no word to select, nothing for search to match, and a screen reader finds an empty page.
Telling them apart takes one second. Drag across a line. If the highlight snaps around the words, the file has real text. A plain rectangle — or nothing — means it is an image.
Text recognition reads the picture and writes the letters in
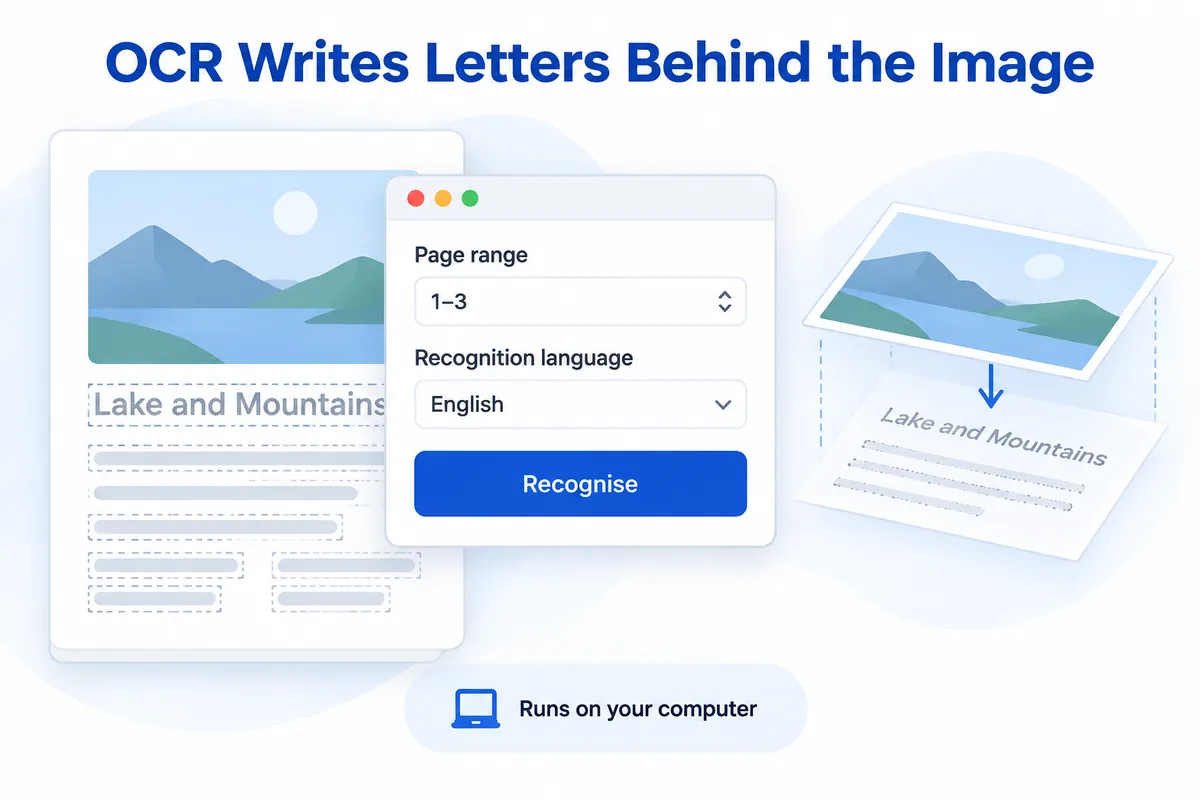
OCR decides which shapes are which characters and writes them into the file, usually invisibly beneath the image. The page looks identical; search and copying start working.
Two limits are worth knowing. OCR does not improve the picture — a faint scan stays faint. And it is a reading, not a guaranteed transcript: figures, names and dates deserve a glance before you rely on them.
In HanFlow PDF the recognition runs on your own computer, with the recognition data installed alongside the application, so it keeps working with no network at all.
Quality is decided before you press the button
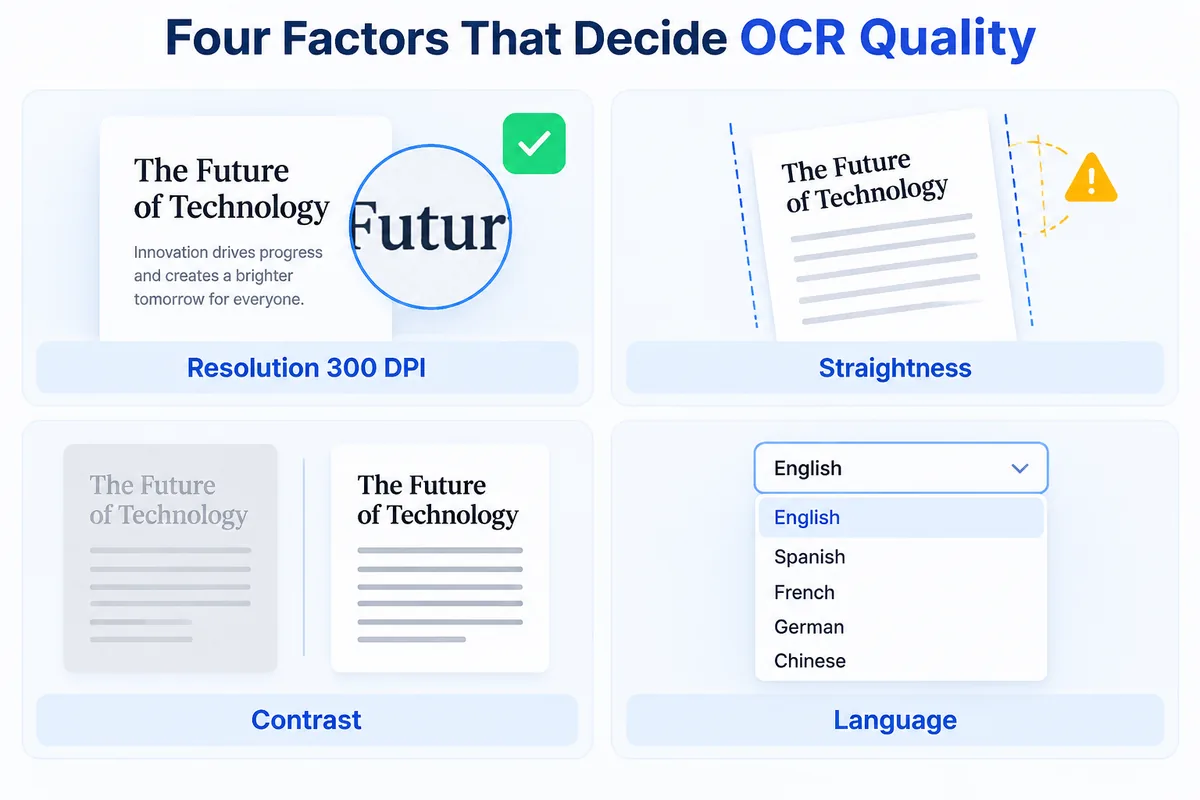
- Resolution — about 300 DPI suits ordinary print. Lower merges thin strokes; much higher only adds weight. Small print is the exception.
- Straightness — a few degrees off square makes recognition markedly harder. Straighten before recognising.
- Contrast — grey on grey is the most common failure. A crisp black-and-white scan beats a beautiful colour scan of a faded original.
- Language — choose it before the run. Finding out afterwards costs the whole job.
Borderless tables, handwriting and stamps across text are genuinely hard. No setting fixes them.
Exporting to Word is a second, separate step
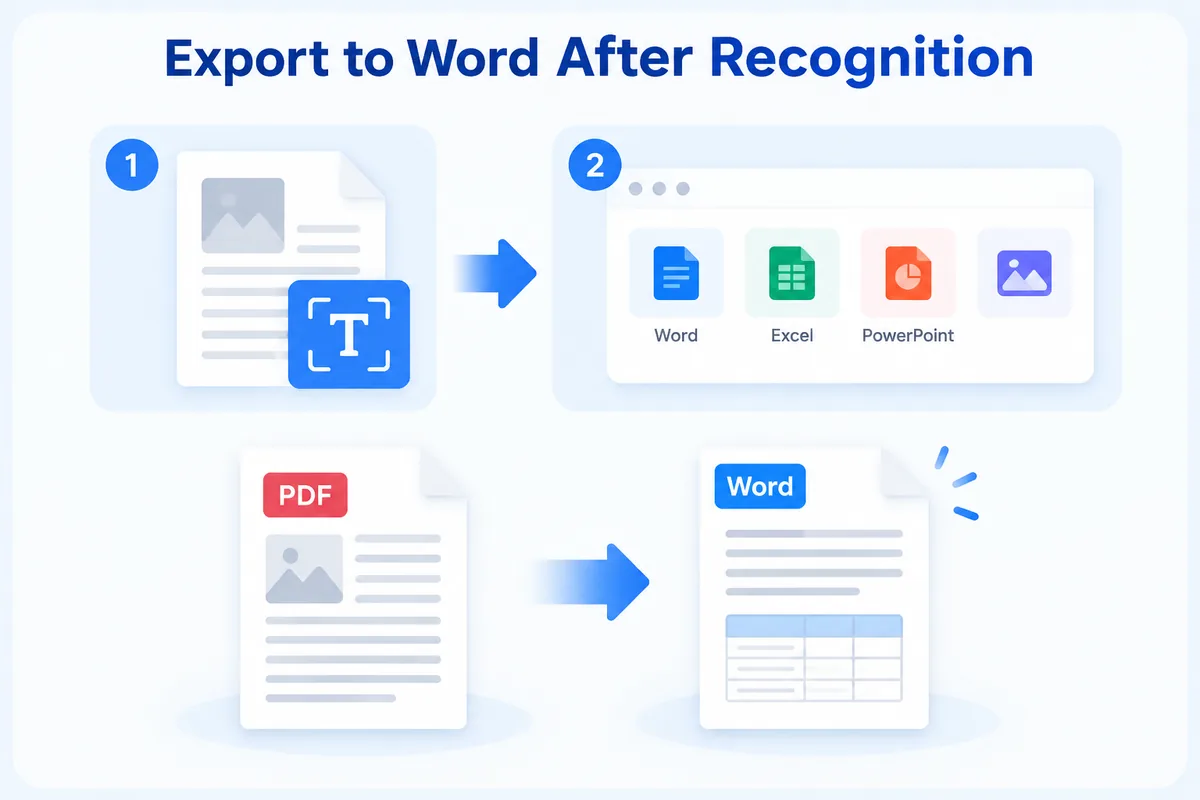
Recognition gives you characters and their positions. A Word file wants paragraphs, headings and tables. Conversion has to infer that structure from position — good on a plain report, poor on a magazine layout.
A workable order:
- Check the scan is straight and legible; rescan bad pages rather than fixing them later.
- Recognise with the right language, over the pages you actually need.
- Select a line and search a word you can see, to confirm it worked.
- Export, then read the result against the original once.
Common questions
Can I use a phone photo? Often, yes — shoot the page flat, in even light, filling the frame.
Why did only some pages fail? Recognition runs page by page, so a darker or crooked page fails on its own.
Does it change how the page looks? No. The text goes behind the existing image.
Text is right but the Word layout is wrong. Different steps. Reading characters is the easy half; inferring structure is where it breaks.
More than one language? Yes, if both are selected before the run.
In short
A scanned PDF is a picture until something reads it. Recognition adds the missing letters; conversion then rebuilds structure — two steps, two different failure modes. Most of the quality is decided by the scan you start with.
HanFlow PDF handles both steps on the desktop. See what it covers on the HanFlow PDF site.